Model Compression
Variational Autoencoder
Model Distillation
Specialised Hardware
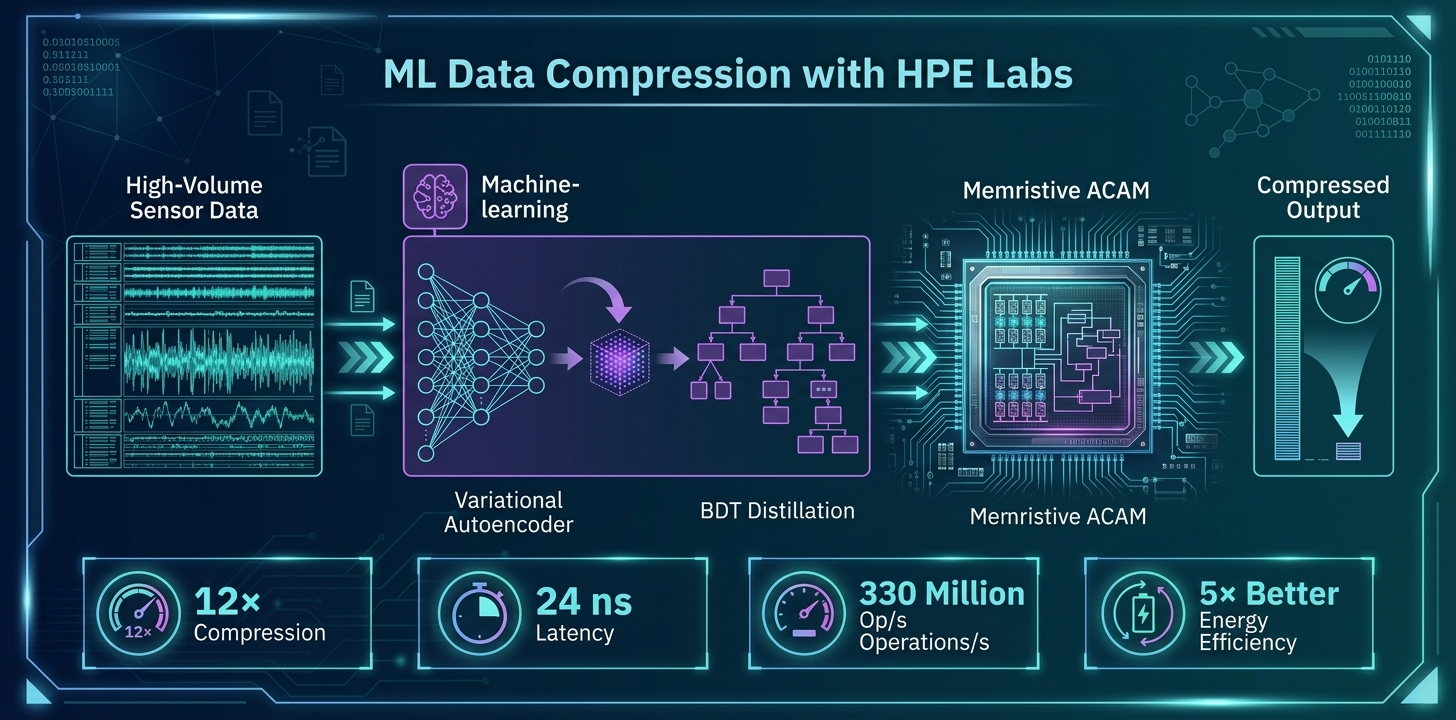
I led an industry–academic study with Hewlett Packard Enterprise Labs on compressing high-rate sensor data. The work combined a variational autoencoder, boosted-tree distillation and specialised hardware implementation.
Results
- 12× data compression
- 24 ns inference latency
- 330 million operations per second
- 5× better energy efficiency than the baseline
- Systematic evaluation of accuracy, latency, throughput, memory and energy use
Publication
Co-author of “Memristive tabular variational autoencoder for compression of analog data in high energy physics”, arXiv:2602.15990. Submitted to Nature Communications.
Tech Stack
Python, PyTorch, variational autoencoders, boosted decision trees, model distillation, quantisation and hardware-aware ML.