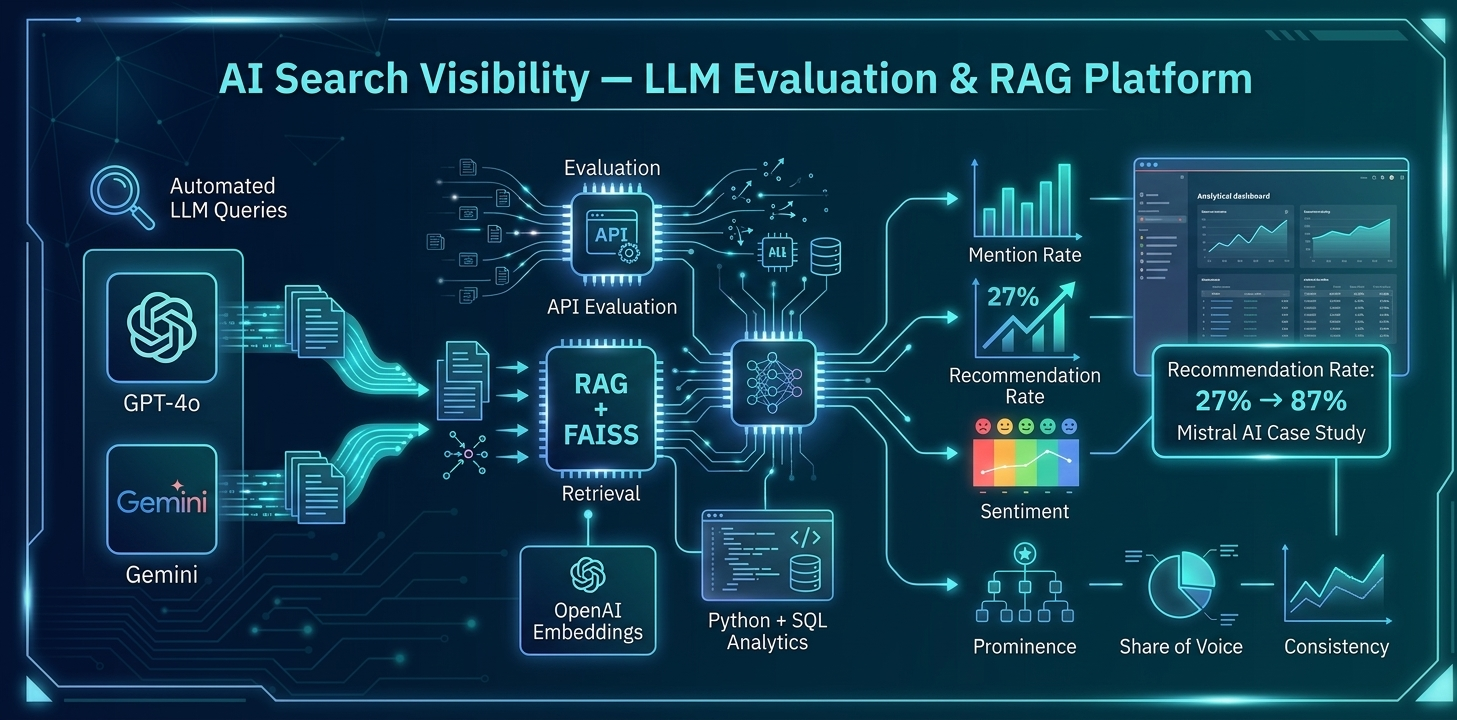
LLM Evaluation
GPT-4o
Gemini
RAG
FAISS
BigQuery
A Python and Streamlit platform that queries GPT-4o and Gemini through APIs and measures how brands appear in AI-generated answers. It evaluates mention rate, prominence, sentiment, share of voice, recommendation rate and consistency.
What I Built
- Automated LLM querying across multiple models and prompt categories
- Repeatable evaluation across six clearly defined metrics
- Retrieval-augmented generation using FAISS and OpenAI embeddings
- Deterministic Python and SQL calculations for traceable results
- Scheduled evaluation using BigQuery, Google Cloud Storage and GitHub Actions
- A tested Streamlit application with 26 automated tests
Example Result
In a case study for Mistral AI, the RAG workflow increased recommendation rate from 27% to 87% and mention rate from 53% to 100%.
Tech Stack
Python, Streamlit, GPT-4o, Gemini, OpenAI embeddings, FAISS, SQL, BigQuery, Google Cloud Storage and GitHub Actions.